
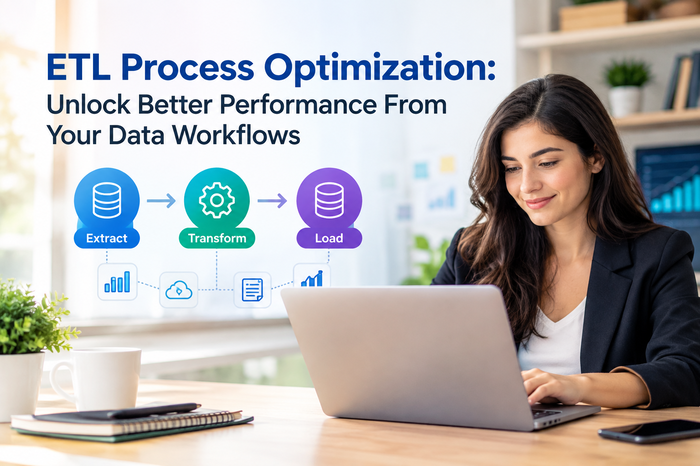
Modern businesses often work with data from multiple sources, including CRM platforms, databases, applications, spreadsheets, APIs, and cloud services. Bringing this information together is essential, but poorly designed data workflows can become slow, difficult to maintain, and expensive to operate.
This is where ETL process optimization becomes important. By improving how data is extracted, transformed, and loaded, teams can create workflows that are easier to manage and better prepared for growing data volumes.
Optimization does not always mean rebuilding an entire ETL system. In many cases, small improvements to data extraction, transformation logic, scheduling, and monitoring can make a noticeable difference.
Why ETL Workflow Performance Matters
An ETL pipeline usually involves several connected stages. Data must be collected from source systems, processed according to business requirements, and delivered to a destination such as a data warehouse or reporting system.
When one stage becomes inefficient, it can affect the entire workflow.
Common problems include:
- Slow data extraction
- Repeated processing of unchanged records
- Complex transformation logic
- Large volumes of unnecessary data
- Failed jobs and repeated runs
- Poor error tracking
- Increasing processing costs
- Delays in reporting and analytics
A well-planned optimization strategy focuses on finding these bottlenecks and improving the specific stages responsible for them.
1. Reduce Unnecessary Data Extraction
One of the simplest ways to improve an ETL workflow is to avoid moving data that does not need to be processed.
Extracting an entire database every time a pipeline runs can consume processing resources and increase execution time. Instead, organizations can consider incremental extraction when the source system supports it.
Use Incremental Data Where Possible
Incremental processing focuses on new or changed records instead of repeatedly processing the complete dataset.
Depending on the system, this may involve:
- Timestamps
- Change-tracking fields
- Transaction IDs
- Database change logs
- Record version numbers
For example, if only 2,000 customer records changed since the previous run, processing those records may be more efficient than processing millions of unchanged records.
2. Simplify Transformation Logic
Transformation is often one of the more demanding parts of an ETL workflow. Data may need to be cleaned, formatted, joined, filtered, validated, or converted before it reaches its destination.
Complex transformation logic can make pipelines harder to understand and troubleshoot.
A practical approach is to review transformations regularly and remove unnecessary operations.
Keep Transformations Focused
Ask whether each transformation is actually required.
You can improve maintainability by:
- Removing duplicate calculations
- Simplifying complicated queries
- Filtering data earlier when appropriate
- Reusing common transformation logic
- Separating complex workflows into manageable steps
Clear transformation logic also makes it easier for another team member to understand and maintain the pipeline later.
3. Process Data in Smaller Batches
Processing a very large dataset as one operation can create resource pressure. Depending on the workflow, dividing data into smaller batches can provide better control over processing.
For example, instead of handling millions of records in one operation, a pipeline can process manageable groups of records.
Batch processing can help with:
- Memory management
- Error handling
- Job recovery
- Processing control
- Monitoring
The ideal batch size depends on the infrastructure, data volume, transformation complexity, and destination system. Testing different configurations can help identify an appropriate balance.
4. Improve Data Quality Before Loading
Performance is important, but optimization should not come at the expense of data quality.
Invalid, duplicated, incomplete, or incorrectly formatted records can create problems later in reporting and analytics.
A stronger ETL workflow includes appropriate validation checks before data reaches its final destination.
Add Practical Validation Rules
Depending on the data, validation may check:
- Required fields
- Data types
- Duplicate records
- Invalid values
- Missing information
- Formatting consistency
- Relationship constraints
It is also useful to separate invalid records from successful records when possible. This allows the main workflow to continue while giving the team a clear path for investigating problematic data.
5. Use Parallel Processing Carefully
Some ETL workflows contain tasks that do not depend on each other. Running these tasks sequentially may unnecessarily increase the total processing time.
Where the architecture allows it, independent operations can sometimes run in parallel.
For example, if customer data and product data come from separate sources and do not depend on one another during extraction, those tasks may be processed concurrently.
However, parallel processing should be introduced carefully. Running too many operations at once can put additional pressure on databases, servers, APIs, or other infrastructure.
The goal is controlled concurrency rather than simply running everything simultaneously.
6. Monitor the Pipeline Continuously
Optimization should not be treated as a one-time project.
Data volumes change. Source systems evolve. New transformations are added, and business requirements become more complex. A workflow that performs well today may become inefficient later.
Monitoring helps teams identify performance changes before they become major problems.
Useful metrics can include:
- Total pipeline execution time
- Records processed
- Failed records
- Processing rate
- Resource usage
- Job failure frequency
- Individual task duration
Tracking these metrics makes it easier to identify which part of the pipeline requires attention.
Building a More Scalable ETL Workflow
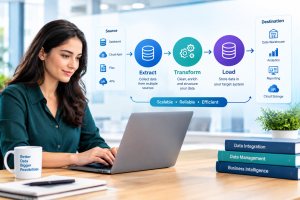
Effective ETL process optimization should support both current requirements and future growth.
Before making major changes, document the existing workflow and identify its main bottlenecks. This creates a baseline for measuring whether an optimization actually improves performance.
A useful process is:
- Measure current performance.
- Identify the slowest or most resource-intensive stages.
- Determine the likely cause.
- Make one targeted improvement.
- Test the change with representative data.
- Compare the results against the original baseline.
- Monitor the workflow after deployment.
This approach reduces the risk of making changes without knowing whether they actually solve the underlying problem.
How Better ETL Workflows Support Data Management
Efficient ETL workflows can make data operations easier to manage as organizations add more systems and larger datasets.
When extraction is controlled, transformations are organized, validation is consistent, and pipeline performance is monitored, teams have a clearer foundation for downstream analytics and reporting.
For organizations looking to explore the topic further, this ETL process optimization guide provides additional context on improving data workflows and processing efficiency.
Final Thoughts
ETL performance is influenced by many factors, so there is rarely one optimization technique that works for every workflow. The most effective approach is usually a combination of better extraction methods, simpler transformations, controlled processing, data validation, and continuous monitoring. Tools and solutions such as ExtractMails can also support organizations in handling email-based data extraction and integrating structured information into broader data workflows.
Start by identifying the biggest bottleneck instead of changing everything at once. Measure the existing workflow, make targeted improvements, and track the results.
With a structured approach to ETL process optimization, businesses can build data workflows that are easier to maintain, more responsive to changing requirements, and better prepared for increasing data demands.
Frequently Asked Questions
1. What is ETL process optimization?
ETL process optimization involves improving the extraction, transformation, and loading stages of a data pipeline to make processing more efficient, reliable, and easier to maintain.
2. How can I make an ETL pipeline faster?
Start by identifying the slowest stages. Incremental extraction, efficient transformations, appropriate batch sizes, and carefully managed parallel processing can help improve pipeline performance.
3. Why is incremental data processing useful?
Incremental processing focuses on new or changed records instead of repeatedly processing an entire dataset. This can reduce unnecessary work when the source system supports reliable change tracking.
4. How does data validation affect ETL workflows?
Validation helps identify incomplete, duplicate, incorrectly formatted, or invalid records before they reach the destination. This can improve the reliability of downstream data.
5. How often should an ETL pipeline be optimized?
There is no fixed schedule. Performance should be reviewed when data volumes increase, source systems change, processing times rise, or new workflow requirements are introduced. Continuous monitoring can help identify when optimization is needed.
Visit us: https://www.smilebox.co.za